Category: Datatards

Here you can observe the biggest nerds in the world in their natural habitat, longing for data sets. Not that it isn’t interesting, i’m interested. Maybe they know where the chix are. But what do they need it for? World domination?

[OC] Every FDA-classified US Dog And Cat Food Recall Since 2012 (271 Recalls, 1,265 Products, Lot Codes, Dates), CSV, CC BY 4.0

FDA publishes pet food recalls only through its Data Dashboard and Enforcement Report search. There’s no bulk download for pet food, and openFDA’s recall data barely covers it. So I built one.

  • recalls.csv: one row per recall, with dates (initiated, classified, terminated), class, firm, reason category and species
  • products.csv: one row per product, with description, UPCs, lot codes, recall number and quantity
  • excluded.csv: every veterinary row I filtered out (drugs, livestock feed…) with the reason, so you can check the filter

One finding: the median time from a company starting a recall to FDA classifying it dropped from 139 days (2012–2019) to 30 days (2020 on), and it dropped in every class. Recalls started in 2020–2023 have all had years to be classified, and their median is 28 days, so the drop isn’t just recent recalls still waiting.

Page + docs: https://perbowl.com/recalls/dataset/

Also on Kaggle (with a starter notebook), GitHub and Zenodo (DOI 10.5281/zenodo.23255873). It’s updated monthly.

Corrections welcome.

submitted by /u/greencalculus
[link] [comments]

Source For Streaming Subscription Prices Per Country (Netflix, Disney+, Max, Prime Video Etc.)?

I’m building a streaming price comparison and need monthly subscription prices per plan, in local currency, for ~60-100 countries. Services: Netflix, Disney+, Max, Prime Video, Apple TV+, Hulu, Peacock, Paramount+, Crunchyroll, plus regional ones like Viaplay and SkyShowtime.

What I’ve found so far:
– tompec/netflix-prices on GitHub: great, but Netflix only
– Global App Store Price Index (OpenTheRank): 18 countries, one plan per service, App Store prices
– Subscription Land / geopriced: good coverage for a few services, but no API or reuse licence
– TMDB/JustWatch API: availability only, no subscription prices

Is there an open or licensable dataset/API that covers more services and countries? Or is scraping each service’s own pricing pages the only realistic option?

Paid sources are fine too if the licence allows showing prices on a public site.

submitted by /u/BingeBossTv
[link] [comments]

How It Works: Selling Your Data To Ai!

Hey all, welcome. Quick intro since this place is brand new.

I run Sanctus Data Labs. We help business owners sell their operating data to AI companies. I started this sub because the questions I get on calls are the same ones I see asked (badly answered) all over Reddit, and there’s no good place to talk about this market honestly. So here’s the primer.

What are AI companies actually buying? Who’s buying? What’s it worth? What do we say when we hear “I don’t trust AI companies with my data.”?

What’s this sub for?

– Questions about selling or licensing business data, from owners, operators, finance people, whoever

– Sharing what you’ve been offered, ads you’ve seen, deals that went sideways (anonymize stuff obviously)

– Discussion of the buyers, the labs, the contracts, the privacy side

Ground rules

  1. Be useful. No low-effort spam or “DM me for a deal” posts.
  2. Disclose if you’re a buyer, broker, or vendor. I’ll go first: I’m a broker/buyer.
  3. Don’t post anyone’s actual data or identifying details.

If you want the long version, I wrote it up here: sanctusdatalabs.com/sell-business-data

Otherwise drop a question below. What’s the one thing you’d want to know before selling your company’s data?

submitted by /u/sanctusdatalabs
[link] [comments]

Looking For Paired-camera ColorChecker Photos With Documented Lighting And Processing

I’m developing LUTloom, a browser color tool with planned paid LUT export, and looking for existing images to evaluate chart correction and camera-to-camera matching.

Ideally, the data would include:

  • The same static scene photographed by two cameras under unchanged lighting.
  • ColorChecker Classic 24 shots and ordinary-scene photos from compatible camera settings.
  • Camera/exposure/WB details, chart identity and an explanation of image processing. sRGB PNG/JPEG copies alongside originals would help.
  • A licence or owner permission allowing private commercial development and evaluation.

I’ve reviewed Beyond RGB and am awaiting clarification about its capture conditions. Other suitable sources would be welcome, especially small sets with clear documentation.

Could anyone point me to an existing dataset or their own suitable test images? Public source links are ideal. Please don’t take new photos or upload private files for this request.

submitted by /u/TravelInPanic
[link] [comments]

Looking For European Mortgage Loan-level Data For Survival Analysis (Master’s Thesis)

Hi everyone!

I’m a Master’s student in Statistics at the University of Padua (Italy), currently developing my thesis on the application of Survival Analysis and Machine Learning to mortgage credit risk.

I’m looking for a European residential mortgage dataset with longitudinal loan-level observations, ideally containing:

– Loan characteristics (LTV, interest rate, loan amount, maturity, etc.).

– Repayment or performance histories.

– Default events and their timing.

– Early repayment/prepayment events, if available.

– Enough information to reconstruct loan durations and right-censoring.

My goal is to compare traditional survival models (such as Cox proportional hazards) with Survival Machine Learning methods, potentially including competing risks for default and prepayment.

I’m aware of the Freddie Mac Single-Family Loan-Level Dataset, but I would particularly like to explore European mortgage markets.

So far, I’ve investigated European DataWarehouse, De Nederlandsche Bank, and several academic studies using proprietary banking datasets. I’ve also contacted some institutions to enquire about academic access.

Does anyone know of other European mortgage datasets, research repositories, or academic collaborations that might be worth exploring?

I’m also interested in datasets that aren’t publicly downloadable but might be accessible to university researchers under specific agreements.

Any suggestions, relevant papers, or contacts would be greatly appreciated.

Thanks in advance!

submitted by /u/Best_Celebration_933
[link] [comments]

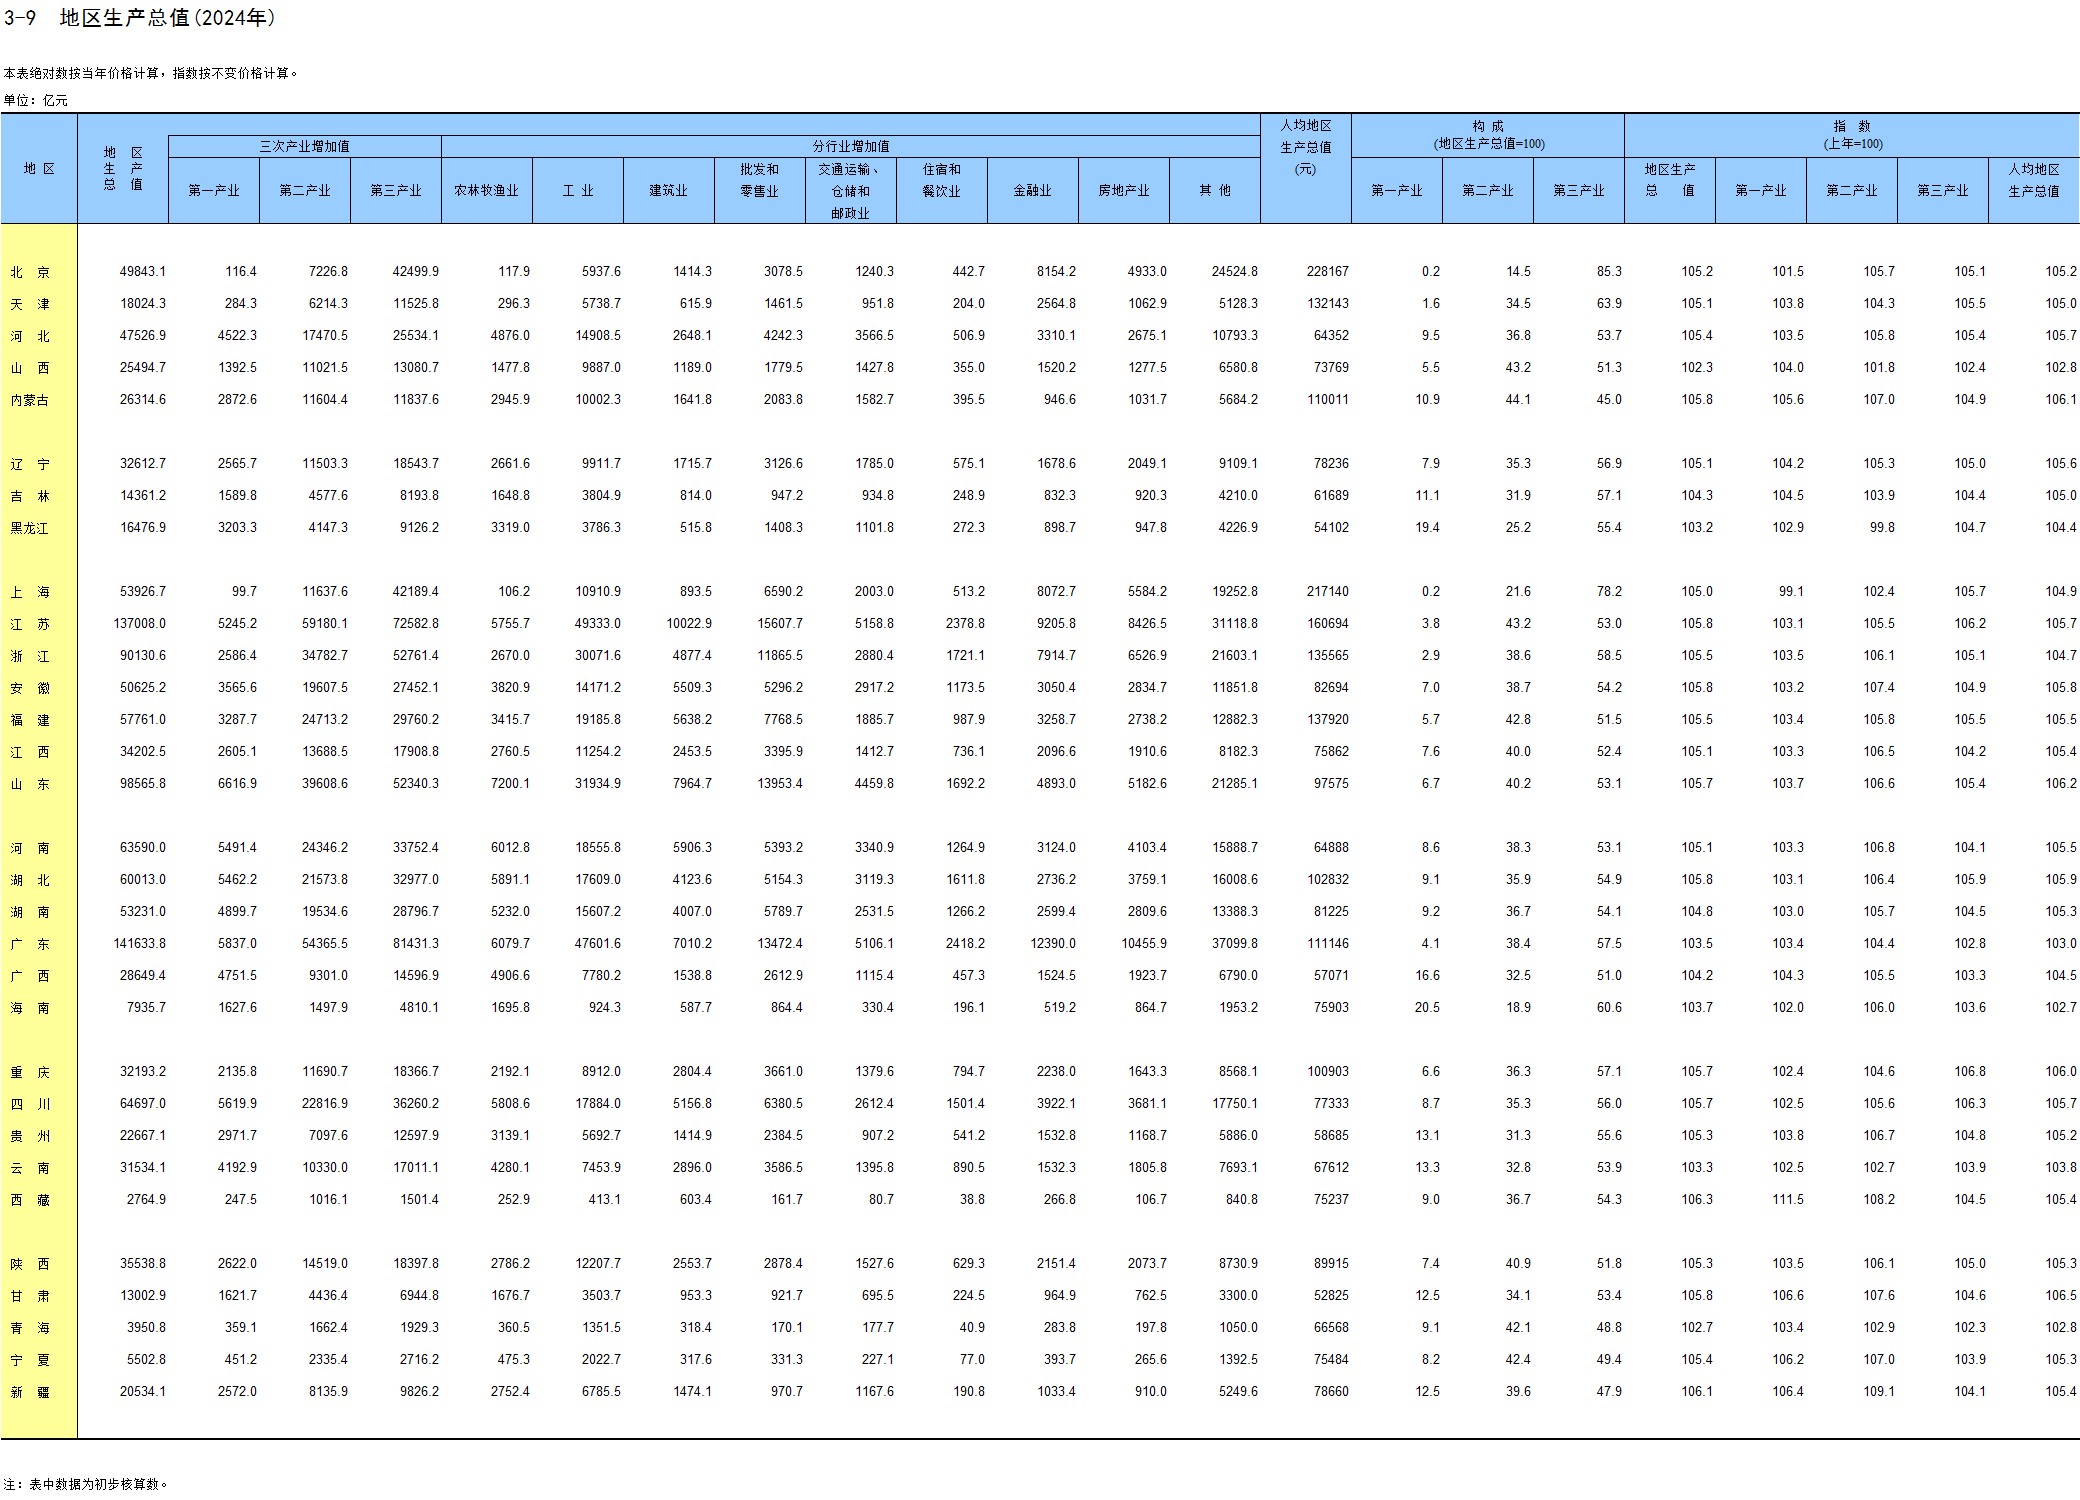
[Self-promotion] Sum Of China’s 31 Provincial GDP Figures Vs The National Total, 2015-2024 (read Off Yearbook Image Tables) – CSV + Figure, CC BY 4.0

China publishes GDP twice over: one national figure, and a separate figure for each of its 31 provincial-level units. Added up, the 31 do not match the national total, and the sign of the gap flipped in 2019.

The columns in the CSV

  • provincial_sum_trn – my addition of the 31 provincial GDP values as printed in the China Statistical Yearbook regional table (table 3-9, one edition per data year)
  • national_prelim_trn – the national figure from that year’s GDP communique
  • national_rev_trn – the latest revision of the same year (routine verification, or the fourth/fifth economic census)
  • gap_vs_prelim_pct – the difference between the first two, in percent

Ten rows, 2015-2024. Trillion yuan, current prices, as printed after conversion from 亿元. The gap is +6.81% in 2015, +1.60% in 2018, then -0.35% to -0.77% every year from 2019 on, the first year accounted under the unified regional accounting system.

Files (CC BY 4.0)

Method, and the caveats that matter

The yearbook’s regional tables are published as images, not as tables, so the 31 values for each year were read off the scan twice – an OCR pass and a separate visual read – and the two reads compared before use. The 2020 column was additionally re-summed a third time (1,012,415.02 亿元, +0.001% against the CSV).

Every row is one fixed vintage. NBS revises both levels – routine verification, and the fourth and fifth economic censuses – so a single year can carry two or three different official numbers. That is why the two national columns are both there: national_rev_trn shows how large the revision is per year, and measured against the later vintages the gap for 2019-2024 runs from -0.10% to -1.00%, with 2023 at -3.35% after the fifth economic census. Nothing here is a forecast.

Source: National Bureau of Statistics of China – the yearbook regional table (e.g. table 3-9, 2025 edition, a scan) and the annual GDP communiques. The underlying statistics are theirs, not mine.

Disclosure: I compiled and host these files (GitHub, CC BY 4.0).

submitted by /u/Head-Manager6402
[link] [comments]

Anyone Here Have Old GPT-3.5-Turbo-0613 / 16k Outputs Or Benchmark Logs?

I’m helping out with a community research project trying to preserve and study the behavior of older GPT-3.5-Turbo models, particularly 0613 and 16k.

I’m trying to find any existing data from when these models were available, especially:

1)prompt/response datasets or cached model outputs

2)old benchmark runs with individual predictions

3)API logs containing model responses

4)token-level logprobs or top-token alternatives, if available

5)public datasets, repositories, or papers that might point us to any of the above

Even a small collection would be useful! We’re particularly interested in data where the model version and collection method are documented, so we can distinguish verified historical outputs from data collected through other providers or newer models.

If you’ve saved anything like this, or know of a repository or person I should look into, I’d really appreciate a pointer.

Thanks :-))

submitted by /u/New_Today172
[link] [comments]

Looking For A RECENT Public Email Dataset With Full Headers (phishing And Legitimate)

I’m researching phishing detection that combines email header evidence with URL evidence. The public datasets I’ve found are either old (Enron, SpamAssassin, Nazario), synthetic (LLM-generated), malicious-only, or text-only with no headers

Does anyone know of a recent public dataset of real legitimate and phishing emails with full headers (.eml or raw)? Datasets that also include QR codes in the emails would be great, but that’s optional. If one exists with a license that allows research use, please share it.

Thanks!

submitted by /u/Omadany
[link] [comments]

The Moment We Decided To Stop Building Our Own Data Layer

we run a small fund and we built a rudimentary system that tracks total headcount over time for the companies we watch. what we actually wanted was headcount by department over time, because total headcount moves too slowly to tell you anything and department level is where the signal is.

we never put much time into it because scraping is a pain, and we do not want to become a data provider. i want the team spending its time on the analysis, not on deciding which proxy to buy this month.

so we looked at buying instead. one vendor has this pattern where you fetch ids first and then collect the data in a second call, which strains our infra and works out around 8 cents a returned company. another returns great data at roughly the same price. most of the rest dont have enough filters to be worth it. and a flat file means we host it ourselves, which is a whole feature build.

where did you draw the build versus buy line on this? and has anybody found department level headcount over time as an actual field rather than a crawl

submitted by /u/_marlowe_
[link] [comments]

Does Anyone Know A Truly Point-in-time US Corporate-actions / Security-identity Dataset With Revision History And Delisted Coverage?

We need effective-dated ticker/security identity, delistings, mergers, splits, dividend events, original announcement knowledge-time, revisions/cancellations, and preferably immutable historical versions rather than a corrected current-state table.

Free/open is ideal, but I’m also interested in datasets people have built themselves or vendors worth evaluating.

The key requirement is: what was known at time T must be reconstructable later without future corrections leaking backward.

If you’re building a data API, historical dataset, parser, or research infrastructure in this area, feel free to reply or DM. We are willing to stress-test it and return reproducible failure cases rather than generic feedback.

submitted by /u/Wild-Raspberry-1770
[link] [comments]

15,908 Answers From 378 AI Models To The Same 87 Prompts, May 2024 To Now (CC BY 4.0)

Since May 2024 every new model got the same prompts: draw a pelican on a bicycle as an SVG, build a landing page in one HTML file, tell five jokes, pick a favourite film, 87 in all. One attempt each, no system prompt, temp 0.7. I kept every answer, and it’s now a dataset:

  • JSON Lines, one file per question, plus models and questions
  • SVG drawings as given, HTML pages with a 1280×800 screenshot each, image and audio answers as files
  • release dates, and which of the 378 models are retired (101 aren’t served on OpenRouter anymore)
  • CC BY 4.0, DOI 10.5281/zenodo.23305275

GitHub: https://github.com/museumofmodels/collection Zenodo: https://doi.org/10.5281/zenodo.23305275 Browse it: https://museumofmodels.com

Nothing is scored, it’s just the raw answers. Happy to hear what would make it more useful.

Disclosure: I made the museum and the dataset.

submitted by /u/sirjoaco
[link] [comments]

[Dataset] Instagram Follower Networks, Suspicious Spikes, And Possible Coordinated Activity

With parliamentary elections approaching in Serbia, numerous Instagram accounts critical of the ruling government have experienced sudden waves of suspicious followers, sometimes thousands within just a few hours.

We’ve collected around 1.3 million follower records and published them as an open dataset on Hugging Face:

https://huggingface.co/datasets/gavrilo/botijada

The dataset includes follow timestamps and pseudonymized account IDs that remain consistent across different profiles.

There are quite a few interesting directions to explore here: temporal patterns, shared followers between accounts, network structures, clustering, anomaly detection, and potentially signs of coordinated activity.

I’m sharing this mostly because I think there’s a lot of room to experiment with the data, especially if you’re into graph analysis, data visualization, or finding interesting patterns in messy real-world datasets.

Feel free to play around with it, build something, or share whatever you discover. I’d be genuinely interested in seeing different approaches and interpretations.

submitted by /u/gavrilo91
[link] [comments]

TikTok APIs For Profile Data, Video Search, Comments, And Analytics

If you’re building a TikTok analytics dashboard, creator research tool, or social listening project, choosing a data source can be a little confusing. Some APIs focus on authorized account integrations, while others provide read access to public profiles, videos, and comments.

Here are a few approaches worth comparing, depending on the data you need and how much infrastructure you want to manage.

1. SteadyAPI TikTok API

SteadyAPI TikTok API provides read-only access to TikTok data through a REST API.

  • Profiles: Usernames, bios, follower counts, and other public profile fields.
  • Videos: Video details, descriptions, authors, engagement counts, and media metadata.
  • Comments: Retrieve comments and replies through separate endpoints.
  • Discovery: Hashtag lookups, video and user search, explore results, and search suggestions.
  • Input: Many profile and video lookups accept a username or URL; shortened links can be resolved to IDs.
  • Pricing: The Starter plan lists 10,000 requests per month at $14.95/month. Higher-volume plans are available.
  • Documentation: TikTok API docs

Some search operations and account video listings require a session managed by the provider. Check the documentation for endpoint-specific requirements and request weights.

2. TikTok for Developers

TikTok for Developers is the natural starting point for official integrations. Available APIs and permissions depend on the product, app review, user authorization, and use case. Check whether the official APIs expose the data your project needs before choosing a third-party service.

3. Apify

Apify offers a marketplace of web data extraction tools, including third-party TikTok actors. Capabilities vary by actor, so check which endpoints and fields are supported, how frequently the actor is maintained, and whether the pricing fits your workload.

4. Bright Data

Bright Data provides web data collection infrastructure and scraping products. It may be worth evaluating for larger collection jobs or projects that need more control over data extraction and delivery.

5. Data365

Data365 offers social media data APIs. Compare its current TikTok coverage, supported fields, usage limits, and pricing against the specific profiles, videos, or search results you need.

submitted by /u/cliffngong
[link] [comments]

[Self-promotion] Free Daily US Job Openings Index From 18,000+ Employers’ Own Career Sites (CSV, CC BY 4.0)

I run VeritaHire, which reads job postings straight from US employers’ own career sites (Workday, Greenhouse, iCIMS and others) every day, about 2.5 million live postings right now. From that I publish a daily Job Openings Index, free on GitHub:

https://github.com/veritahire/us-job-openings-index

– Daily since Sept 4, 2026 (= 100), published the next morning around 08:25 UTC

– Fixed panel: 18,310 employers, 2,081,433 open postings as of Oct 10

– Columns: daily index, 7-day average, the first-published value (every first print is kept, so revisions are visible), panel size, weekly new-posting and closing rates

– CSV, CC BY 4.0, refreshed every morning by a GitHub Action

Latest: 101.06 (7-day average) through Oct 10, +1.13% over 28 days. Method: https://veritahire.com/job-openings-index/

submitted by /u/SpiteMaximum3570
[link] [comments]

[self-promotion] 2024 Population Growth: 217 Country/area Observations In One CSV

Original source: World Bank WDI, SP.POP.GROW.

Disclosure: I work on Global Data Tracker, which hosts the CSV mirror below. The underlying population data are from the World Bank and its listed providers.

This fixed-2024 extract has 217 unique country/area IDs, no aggregate rows and no missing growth values: 42 negative and 175 positive. All 217 values matched the current World Bank response when checked on October 11.

Columns: country_id, country, value, unit, year, source, publication, provider_footnote, source_context, context_sources. The final three fields are blank in this release. IDs follow World Bank country/economy codes; don’t assume every key is ISO.

The rate is 100 × ln(midyear population 2024 / midyear population 2023), in percent. It is not ordinary percentage change or a birth rate. Migration, displacement and revisions can affect comparisons; the rate alone does not explain causes. Method.

Download the fixed-2024 CSV, free without an account. Useful for practicing joins and comparing rates rather than population headcounts.

globaldatatracker.com, selecting 2024. License: CC BY 4.0 with World Bank additional terms.

submitted by /u/TrekkingAround10
[link] [comments]

Canadian Geometry Families Over Time, Census, Health Zones, National And Provincial

https://www.daedalmap.com/geometry/canada#country-history

Other countries available, see the patch notes for details of how the packs evolve.

Free downloads, and free geometry tools to use them with, no paywalls or gated services. All original sources are noted for citations and attributions.

There are full detailed shapefiles, display version shapefiles, or just crosswalks to download to see the relationships between places.

Canada and USA are my most detailed packs, also have Great Britian, France, Germany, Australia, Mexico, Brazil, more to come!

submitted by /u/Xyver
[link] [comments]

Dataset Needed For My Research. Teams/slack & Jira.

I’m conducting research on project management and need a dataset that includes Microsoft Teams or Slack messages (messages from other platforms are also acceptable) exchanged within a project managed through Jira.

Ideally, the dataset should contain both the Jira project data and the associated communication history, so the messages can be linked to a specific project created in Jira.
How can I collect or obtain such a dataset for my research?

submitted by /u/Due_Highway7288
[link] [comments]

[Request] [PAID] [self-promotion] $60 Bounty For 30 Original Bilingual Speech Clips

Disclosure: I run DataBazaar and posted this bounty. I am looking for an original, human-recorded code-switching dataset for speech-recognition research/training.

The request is for 30 clips from two consenting adult speakers (15 clips each), using the same language pair throughout. Any language pair is welcome. Each clip should be 5–15 seconds long and contain meaningful speech in both languages, with at least one language switch. Cover at least five everyday topics overall.

Deliverables: – 30 mono WAV or FLAC files, recorded at 16 kHz or higher. – annotations.jsonl with anonymous speaker IDs, verbatim transcripts, and timestamped language segments; a fluent person must check every clip. Keep hesitations and self-corrections, and mark switch boundaries to approximately 0.25 seconds. – README and a dated consent attestation covering redistribution and speech-recognition research/training. Keep personal contact details out of the submission.

Original recordings made for this bounty only: no TTS, voice cloning, spliced speech, or reused corpora. Transcription assistance is allowed if a fluent person verifies the result. Quiet-room recordings and accurate labels matter more than studio equipment.

The bounty is $60 total for one accepted dataset, not $60 per speaker or payment for every submission. Review the complete acceptance requirements before recording. The deadline is November 15, 2026 at 07:59 UTC, and a DataBazaar account is required to submit.

Full requirements and submission: https://databazaar.io/bounties/3b6815b8-b0ad-48e1-8ec5-4f3f8b89d0aa?utm_source=reddit&utm_medium=community&utm_campaign=bilingual-recordings

Existing public corpora would not satisfy this request because it needs new recordings with explicit redistribution consent. Happy to clarify the format or acceptance requirements here.

submitted by /u/fightingowls
[link] [comments]

[self-promotion] 2024 Drinking-water Access: Two CSVs For Comparing Coverage And Missing Values

For anyone practicing country-level joins or exploring water access, these two CSVs use the same reporting year and country IDs:

  • At least basic drinking water: 217 country/area rows, with 202 reported values
  • Safely managed drinking water: 217 country/area rows, with 148 reported values

Original data: WHO/UNICEF Joint Monitoring Programme (JMP), distributed through the World Bank’s World Development Indicators. At least basic source · Safely managed source

Disclosure: I work on Global Data Tracker, which hosts the CSV exports below. They’re free to download without an account.

Download at least basic, 2024 CSV Download safely managed, 2024 CSV

Each file includes country_id, country, value, unit, year, source, publication and provider-note fields. Blank values mean no published observation for that selection; they are not zeros. The files retain all 217 countries/areas, including those with missing values. World and regional aggregate rows are excluded.

A useful exercise: join on country_id, count missing values first, then compare the two percentages for the 148 countries/areas with both observations. “At least basic” already includes safely managed service, so don’t add the columns. Safely managed also requires an improved source on premises, available when needed and free from specified contamination. JMP definitions

These links pin the saved September 19, 2026 release; the observations are for 2024. Checked October 10: the values and missing entries in both files match the current World Bank API. National estimates can hide local differences and may be revised. Release/method notes · World Bank data-use terms and attribution

submitted by /u/TrekkingAround10
[link] [comments]